OpenAI Agents API vs Agents SDK: Who Runs Your Agent?

API, SDK and Responses: what changes in the application?
| Decision | Agents API | Agents SDK | Direct Responses API |
|---|---|---|---|
| Who runs orchestration? | OpenAI's managed service | Your application runs the SDK | Your application or existing workflow engine |
| Where is continuing work represented? | Managed sessions linked to your business tasks | Your chosen session/state integration | Your workflow record plus API state features used |
| How do business tools run? | Application handlers still execute function tools | SDK tools integrate with your application's code | Your dispatcher handles client-owned tool work |
| What is the main engineering trade? | Less runtime operation, an external service boundary | Runtime control plus deployment responsibility | Direct composition plus explicit workflow ownership |
| What survives a runtime change? | Only what you make portable outside the service | Business records and adapters you keep independent | Business records and workflow contracts you retain |
The last row is an architectural recommendation. No product label guarantees portability. A tool implementation may be reusable while its pending-call record, approval state and result envelope still need adaptation.
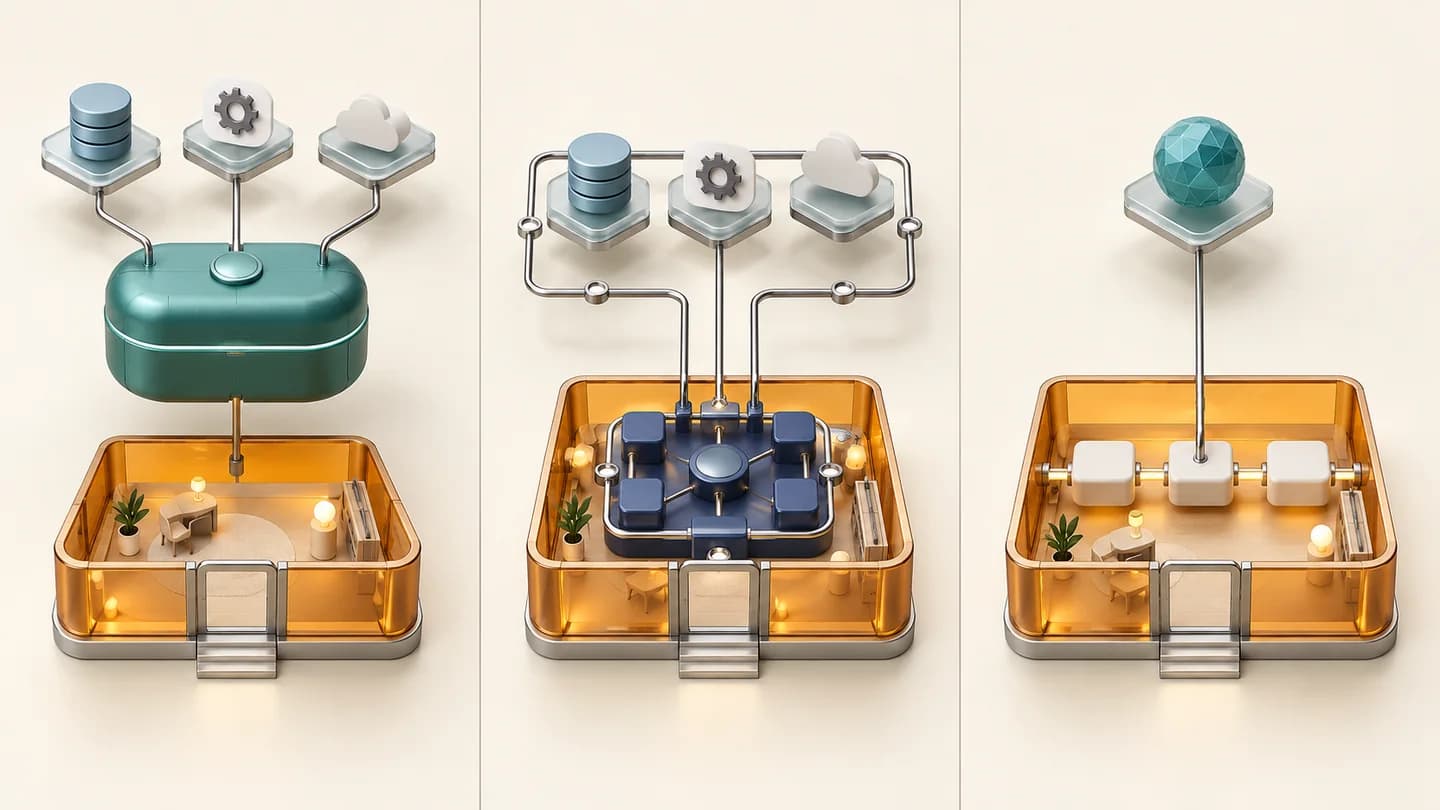
Will Agents API replace LangGraph or your existing agent framework?
Our assessment is that replacement depends on what the framework does in your product. If it primarily maintains a generic model/tool loop, a managed runtime may replace a substantial portion of that work. If it encodes business routing, approval transitions, deadlines and durable domain state, those responsibilities still need a home.
For example, an insurance-document workflow might extract information, pause for an authorized reviewer, and send a signed-off result to a downstream system. The reasoning step can change runtime without changing who is allowed to approve. Replacing the whole workflow because one execution step became managed would mix business policy with infrastructure selection.
Inventory each existing component as one of three things: business rule, execution mechanism, or integration adapter. Then identify which execution mechanisms the managed service can actually replace. This is a more useful migration estimate than comparing the number of lines in two quickstarts.
A hybrid is also legitimate. Keep a deterministic outer workflow and delegate a bounded investigation to Agents API. Define a single input, expected evidence and a return condition for that step. Avoid letting both the outer workflow and the inner runtime independently decide when to repeat the same external write.
This is not a claim that every named framework lacks managed features or that one framework is obsolete. The decision concerns the responsibilities in your implementation, not a universal ranking of framework brands.
Sessions, memory and approvals are different kinds of state
RunState. The distinction is who deploys and operates the mechanism, not whether the SDK has memory or approvals.For a refund-review assistant, keep three records conceptually separate:
| Record | Example contents | Why a conversation alone is insufficient |
|---|---|---|
| Working context | Evidence gathered and candidate explanation | It helps reasoning but is not the authorization record |
| Execution state | Current run, pending tool call, continuation reference | It identifies where work can resume |
| Business state | Customer, proposed amount, reviewer, final transaction identifier | It establishes what was permitted and what happened |
These are suggested application records, not three required tables or an OpenAI schema. Their purpose is to make a resumed run answer “is this action still authorized?” before performing it. If a customer cancels while approval is pending, resuming execution should not resurrect the old permission.
With managed sessions, map the service reference to the business job. With the SDK, decide where session and paused-run data are stored and how a worker retrieves them. With direct Responses, define the equivalent continuation in the existing workflow. In every case, test a process restart during approval rather than assuming a successful in-memory demo proves recovery.
Is a private sandbox equivalent to self-hosting the agent?
Map the actual data path. For a database investigation, distinguish the database query, the returned rows, the tool result sent to the model, and the trace retained for debugging. Keeping the database in a VPC does not mean the query result never leaves it.
What if multi-model choice is a requirement?
Keep the model interface and runtime interface separate. For an application using a gateway, access to several models can simplify model selection, but it does not make every provider implement the same session lifecycle or tool protocol.
A practical evaluation has two stages. First compare runtime options with the same model, tools, data and acceptance rules where that is possible. Then evaluate different models within the chosen architecture. If one candidate requires a different model or tool configuration, label the comparison as a whole-system comparison; do not attribute every improvement to the runtime alone.
For an SDK-based route, verify the adapter's actual capabilities: input messages, tool arguments and results, structured output, streaming, usage and error handling. A basic text response is insufficient evidence for a tool-heavy agent. For the managed API, do not infer support for arbitrary gateway models from SDK provider flexibility.
The useful fallback boundary is often a new business task. Route that task to a verified alternative with a fresh execution record. Moving an in-progress managed session to another model or runtime requires a deliberate state conversion and replay policy; changing a base URL is not that policy.
Choose by workload, including when to keep what you have
| Workload and existing system | First candidate | Why it is plausible | What would reverse the choice? |
|---|---|---|---|
| Small team, variable-length research tasks, little existing orchestration | Agents API | Runtime operation is a substantial new burden | Data boundary mismatch or no quality/operating benefit |
| Product with custom approval paths and application workers | Agents SDK | Execution can remain close to existing controls | Worker and state operations outweigh the control benefit |
| Reliable workflow engine with a few fixed model steps | Direct Responses | Reuse the existing state machine | Tasks require an adaptive loop the team cannot maintain economically |
| File-heavy work using specialized internal compute | SDK or managed API with a self-hosted environment | Both deserve evaluation against the actual infrastructure | Required connection, isolation or retrieval path cannot be satisfied |
| Multiple independent evidence-gathering tasks | Managed or SDK orchestration | Parallel work may shorten the critical path | Synthesis cost, duplicate work or verification effort erases the benefit |
Test recovery at the point where a duplicate action becomes possible
Use a non-production ticketing fixture. The task should investigate an issue and create exactly one ticket after approval. Interrupt the client after the destination has accepted the ticket but before the application has recorded the tool result. This is a proposed failure-injection scenario, not a reported provider defect.
Pass this scenario only if the application can explain whether the ticket exists, avoid creating a duplicate, and resume or terminate the task in a known state. If the result is ambiguous, route it to review. Blind retry may make an apparently resilient demo less reliable in production.
Compare accepted-result cost, not just tokens
Use direct charges per accepted result and keep engineering effort separate. Include failed attempts, tools, environments and any rescue work. A runtime can improve operating effort while increasing direct API spend, or vice versa; the trade should be visible.
Migration also has a break-even point. Suppose integration and validation cost an internally estimated $1,200, and a later verified steady workload saves $0.04 per accepted task. Recovering that investment requires 30,000 accepted tasks, before recurring operating differences. These are hypothetical inputs; replace them with your team's data. If the workload will not reach that volume, a small unit saving may not justify migration.
Measure latency in comparable terms: time to first progress, time to accepted artifact, and manual review time. Do not compare a streaming first token with a fully verified report. For environments, record setup and cleanup as well as active processing; that reveals whether cold starts or long waits dominate the result.
Trace export helps diagnosis; it is not a business audit by itself
Nevertheless, an exported trace and an accepted business outcome answer different questions. In the ticket fixture, connect the application job to the runtime trace, tool call and destination ticket. Ask a reviewer who did not run the test to explain why the ticket was created and whether it was authorized. If the evidence cannot support that explanation, exporting more spans alone will not solve the audit gap.
Keep model/tool observations and billed charges as separate inputs until reconciled. Do not treat a dashboard screenshot as proof of final unit economics, or a recorded tool invocation as proof that the downstream change committed.
A migration plan with an actual rollback boundary
- Freeze a baseline. Save task fixtures, tool versions, acceptance checks and current results. Include a long task, an ambiguous input, an approval pause and a failed external action.
- Run paired trials. Use the same model and budgets where possible; record differences where not. Keep multiple attempts for variable tasks and report the sample size, not just the best output.
- Shadow read-only work. Compare candidates without allowing the shadow agent to send messages or duplicate writes. Judge outputs against the same acceptance rules.
- Canary new tasks. Assign the runtime when a new business job starts. Keep that ownership stable through its lifecycle; do not split one ongoing task between two unsynchronized controllers.
- Rollback deliberately. Route new jobs back to the baseline. For in-flight jobs, either drain the existing runtime or reconcile tool effects and artifacts before starting a replacement. Preserve the evidence needed to explain the transition.
Set thresholds before viewing results. Quality must meet the product's existing acceptance requirement; unauthorized writes and duplicate side effects should block rollout; cost and latency budgets should come from the business workload. There is no universal “95% is production-ready” score that replaces those requirements.
A migration example: keep the support workflow, replace its investigation step
Suppose an existing SDK application receives a support issue, gathers account evidence, pauses for approval and creates a ticket. A useful first migration is to replace only evidence gathering. The managed task returns a draft and references; the existing application retains approval and ticket creation. This is a proposed design, not a tested migration result.
| Existing component | Keep or adapt? | Concrete migration work |
|---|---|---|
| User identity, account permissions and ticket schema | Keep the business contract | Give the candidate the same permitted records and required output fields |
| SDK investigation runner | Replace for the pilot step | Start a managed session and map its reference to the existing business job |
| Tool implementations | Reuse where their contract fits; adapt dispatch | Translate arguments and results, preserve permission checks and record tool failures |
Pending approval and stored RunState | Keep with the current owner for in-flight jobs | Finish or reconcile the old run; do not treat its serialized state as a managed-session import |
| UI progress and final result | Adapt the application-facing mapping | Distinguish investigation progress, a draft awaiting review and a successfully created ticket |
| Trace and billing records | Add the new references | Associate each candidate run with the same task, accepted outcome and cost ledger |
The first pilot can therefore end at “draft ready for review.” It need not transfer every part of the workflow at once. If the investigation improves but approval recovery regresses, keep that approval path in the application and narrow the migration instead of accepting an all-or-nothing result.
RunState includes pending work and approval decisions, but deserialization does not authenticate who supplied it. Store it under application control, validate the reviewer against the pending action and coordinate resumption so the same approval is not consumed twice. This is concrete application work that remains even when the investigation runtime changes.FAQ
Does Agents API make existing frameworks obsolete?
It may replace generic runtime work. Business policy, approval transitions and domain state still need an owner. Evaluate components rather than replacing a framework by name.
Is Agents SDK stateless?
No. The SDK documents sessions and persistent implementations. Your application still operates their deployment and storage choices.
Can I preserve human approval with the SDK?
Yes, the documented flow includes interrupted runs and resumable state. Test restart and authorization changes in your own deployment rather than relying only on an in-memory demo.
Does self-hosted compute make Agents API ZDR-compatible?
No, according to the current Agents API documentation. Review the full data path for SDK-based alternatives too; local orchestration alone is not a retention guarantee.
Can I switch runtimes by changing the base URL?
Do not assume that. Tool implementations may be reusable, but sessions, pending calls, state and result handling need an explicit adapter and tests.
Which choice is cheapest?
Measure the same accepted business outcome, including failures and rescue attempts, then include migration and operating effort. The arithmetic above is hypothetical, not a winner declaration.
Can I export traces from Agents API?
The current official docs describe OTLP JSON export. Plan how the exported trace will connect to your monitoring system; consult the EvoLink launch documentation for the available integration path.
Can I use it through EvoLink today?
Sources and scope
Primary documentation is linked beside each technical claim. HN and Reddit are used only to identify the API/SDK and framework questions. Workloads, arithmetic and rollout recommendations are editorial proposals; this article does not claim a controlled runtime benchmark, universal cost saving or production gateway compatibility.