

Gemini 4 Argon vs GPT-6 Astra: Coding, Cost & Access

| Your situation | Start here | Evidence needed before switching |
|---|---|---|
| Astra already passes your coding checks | Keep it serving; replay the same tasks on Argon | Accepted patches, reviewer time and cost per accepted change |
| Long generated reports or large code changes hit output limits | Test Argon with a task-sized output budget | Complete outputs that pass review, within latency and spending limits |
| Your agent depends on Astra-specific Responses behavior | Keep that workflow intact and isolate a portable comparison | Equivalent tool behavior and a measured migration benefit |
| Routine tasks already run cheaply on a smaller model | Retain the cheaper baseline | Improvement over that baseline, not just over Astra |
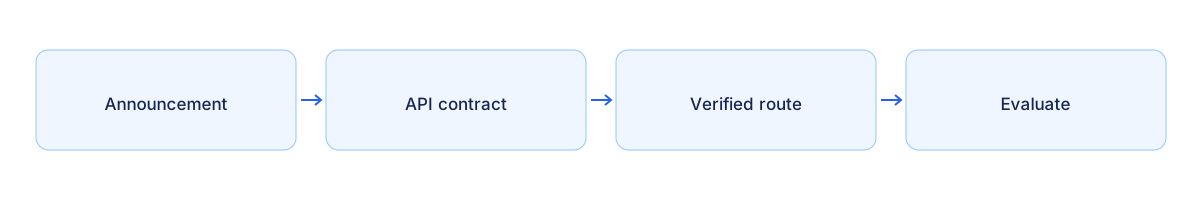
What Is Actually Comparable Today?
| Question | Gemini 4 | GPT-6 Astra | Safe decision |
|---|---|---|---|
| Official product status | Announced · Restricted rollout | Released by OpenAI on September 3, 2026; API access broadened from September 4 | Nominal token rates and provider evaluations can be compared now; a matched EvoLink workload test remains pending. |
| Provider API model ID | Not established by the announcement; use EvoLink’s configured ID from its model page for the gateway | gpt-6-astra (OpenAI); no generic gpt-6 alias | Keep provider IDs and gateway IDs separate; use the selected route’s documented value |
| Published specs (context, output, inputs) | Google announces an output limit of 1M tokens for extended reasoning and generation. This is an output limit, not a confirmed input context window or an EvoLink parameter guarantee. | 1.05M-token context, 128K max output, text and image input, text output (OpenAI) | Do not infer Gemini 4 limits from Gemini 3.x |
| List pricing | Google's announced introductory rates are $2 per 1M input tokens and $10 per 1M output tokens. After the introductory period they become $4 and $20 respectively. The end date is not announced. These are Google rates, not an EvoLink quote. | $10 input / $50 output per 1M tokens; cached input $1 (OpenAI Standard tier) | Nominal token rates and provider evaluations can be compared now; a matched EvoLink workload test remains pending. |
| Tool-calling surface | Not published | Responses API only; OpenAI documents that Chat Completions does not support function calling with Astra | Move tool loops to Responses regardless of the Gemini decision |
| EvoLink route | Available through EvoLink; use the model ID, request example and current pricing on the Gemini 4 page | Callable; request model ID gpt-6-astra | Baseline on the verified route |
| Matched workload test | Run through EvoLink; no results claimed here | Run against your existing baseline | Run a workload-specific comparison through EvoLink while preserving your current baseline, acceptance criteria and fallback during replay, shadow and canary stages. API access enables the evaluation; it does not establish a quality or cost win. |
Google's published evaluations provide an initial comparison, not a matched EvoLink test. They do not establish latency, accepted-task cost or a universal winner. The table below includes both a favorable result and a result where Argon trails the comparison model.
Google-reported evaluation results
| Benchmark | Gemini 4 Argon | GPT-6 Astra |
|---|---|---|
| DeepSWE v1.1 | 77.9% | 74.1% |
| FrontierSWE v2 | 55.0% | 65.5% |
Read the settings before interpreting the gap. Google's methodology uses pass@1 unless noted and generally the highest available thinking settings. DeepSWE combines an Argon run using mini-swe with comparison results from public leaderboards or system cards; FrontierSWE comes from the Proximal leaderboard. These are not two models rerun inside one EvoLink harness. Keep benchmark version, harness, reasoning setting and source beside each score, and do not translate percentage-point gaps into a predicted production success rate.
| Evidence field | DeepSWE v1.1 | FrontierSWE v2 |
|---|---|---|
| Model versions | Gemini 4 Argon / GPT-6 Astra | Gemini 4 Argon / GPT-6 Astra |
| Harness and score source | Argon: mini-swe run; Astra: public leaderboard, as cited by Google | Proximal leaderboard, as cited by Google |
| Reasoning and metric | Google states highest available thinking and pass@1 unless noted; identical model settings are not established | Check the linked methodology for benchmark-specific settings; identical budgets are not established |
| Evidence checked | October 13, 2026; not the date of a matched run | October 13, 2026; not the date of a matched run |
| Interpretation limit | Different result sources; not a controlled EvoLink comparison | Does not predict success on your repository |
Choose an Evaluation Scope Before Moving Traffic
Start with a workload you can score: a repository repair, a document rewrite, or a tool workflow with a known final state. Keep the baseline input, acceptance rubric, retry budget and time limit fixed. Argon's long-output allowance is useful only if the additional output helps complete that task; it is not a reason to raise every request's budget.
Measure the integration work as well as token use: adapting a tool loop, changing state handling and maintaining a second parser can outweigh small per-request savings. Promote only task classes where the observed benefit covers that work.
What Your OpenAI Workflow Would Need to Adapt for Gemini
model string. It does not make provider-native semantics identical: tool schema handling, streaming event boundaries, reasoning controls, cache mechanics, error codes, and the identity returned in the response are still defined by each provider's contract. One API key on a gateway does not guarantee that every provider-native feature behaves the same way across providers. The Argon product page provides the EvoLink integration path. The right-hand column lists compatibility checks for your application, not promises that every provider-native feature is mapped.| Surface | What Astra documents today (OpenAI) | What to verify on the Argon route |
|---|---|---|
| Request/response protocol | Responses, Chat Completions, and Batch endpoints | Use EvoLink’s Chat Completions example or Gemini native format; test your response parser and required fields instead of forwarding a Responses payload unchanged |
| Tool/function schema | Function calling on Responses only; async tool calling documented | Schema format, parallel and async support, tool-choice modes, behavior on forced tool choice; check the selected route documentation and your application trace |
| State and conversation handling | Responses-based state; configuration_update changes effort mid-conversation while preserving cache — supported for standard, single-agent requests; check the documented compatibility limits | How multi-turn state, prior tool results, and cached prefixes are carried between turns; check the selected route documentation and your application trace |
| Streaming | Streaming supported; mid-turn steering via WebSocket response.steer | Event shape, partial tool-argument delivery, usage reporting inside the stream; check the selected route documentation and your application trace |
| Retry and error contracts | Account-tier limits published in the current model documentation; upstream limits are not EvoLink route limits; HTTP 400 on none or minimal effort; misalignment monitoring can stop an API task mid-run | Error codes, rate-limit structure, any safety-interrupt behavior, retry guidance; check the selected route documentation and your application trace |
| Reasoning/thinking controls | reasoning.effort at low, medium, high, xhigh, max; reasoning.mode standard or pro on Responses; temperature, top_p, logprobs rejected | Whether thinking is exposed, budgeted, or always on; which sampling parameters exist; check the selected route documentation and your application trace |
| Prompt caching | Supported; prompt_cache_options.ttl accepts "30m" only; cached input $1 per 1M | Cache mechanism, TTL options, read and write pricing; check the selected route documentation and your application trace |
| Long-context billing | Whole request billed at 2x input and cache, 1.5x output above 272K input tokens | Whether pricing tiers exist and where the thresholds sit; check the selected route documentation and your application trace |
| Gateway route | gpt-6-astra on EvoLink; image input through EvoLink requires separate route verification | Returned model identity, usage counters, and billing record on the EvoLink route; check during integration |
temperature and top_p, and the effort-ladder tuning are Astra-specific work you do now. The Argon column is a compatibility checklist for the route you will use. A shared key reduces account setup, but does not eliminate protocol migration work.Task Matrix: Coding, Multi-Tool Agents, Long Documents
Google positions Argon for software engineering, enterprise knowledge work and cybersecurity defense, and publishes model evaluations. These are provider-reported results, not EvoLink tests or a guarantee for your workload. Nominal token rates and provider evaluations can be compared now; a matched EvoLink workload test remains pending.
| Workload class | What to measure | What Astra lets you measure now | Entry condition for Gemini 4 |
|---|---|---|---|
| Repository-scale coding | Accepted patch rate, human correction time, retries per accepted change, tokens per accepted change | OpenAI positions Astra for coding and complex reasoning; run your task set on Responses at medium and high effort to fix a baseline | Same harness, same task set, same rubric: an accepted-patch rate and cost per accepted patch that meet or beat the frozen Astra numbers, with a published model contract behind the result |
| Multi-tool agents (computer use, browsing, internal APIs) | Whole-trace completion, wrong-tool rate, loop rate, recovery after a failed tool call | OpenAI documents computer use, async tool calling, and mid-turn steering; measure with and without these native features and label the lanes | A published tool-calling and streaming contract, then completion rate on a matched portable lane before any native-feature lane is compared |
| Long documents and research | Retrieval accuracy across the context, output completeness, cost by input-size band | OpenAI documents 1.05M-token context and research and document-creation use; record cost on both sides of the 272K threshold | Published context and output limits, published pricing tiers, the same document set, cost recorded at each input-size band |
| Routine high-volume tasks | p95 latency, cost per task, error rate | Often the right baseline is a GPT-5.6 tier rather than Astra | Must clear the cheaper baseline, not only Astra |
Two rules keep the matrix honest. First, provider-documented positioning is a hypothesis about where to test, never a result. Second, a native-feature advantage (for example, Astra's async tool calls) must be reported as a lane result, not converted into a universal ranking.
For long technical question sets, validate the answer count and schema, independently check sampled derivations, and rerun code tests. A response that uses the available output capacity but omits questions or contradicts earlier answers fails acceptance. Split and retry within the same total task budget.
Integration Cost and Cost per Accepted Task
The unit that matters is cost per accepted task: everything spent to get one task through review, including input tokens, cache writes and reads, output tokens, tool-call overhead, retries, fallback requests, and human correction time. Token price alone hides most of that.
Move from Replay to Shadow and Canary
- Copy the integration contract from the model page. Use EvoLink's current model ID and request example. Keep the route in configuration and record the protocol used for each lane.
- Replay frozen tasks. Use the same repository snapshots, tool permissions, acceptance tests and output budget. Record failures as well as accepted results.
- Shadow a representative sample. Continue serving Astra while scoring Argon's outputs separately. Include long requests and failed-tool recovery, not only short successful examples.
- Canary one task class. Set a traffic share and observation window in advance. Expand only if accepted-task rate, cost and latency meet the thresholds; retain the baseline route for rollback.
Check response metadata, usage and billing together. A returned model label is a useful consistency check, not independent proof of the underlying model's identity. Resolve unexplained routing or billing discrepancies before expanding traffic.
When to Keep Your Current Routing
A released Gemini 4 does not automatically displace Astra or a cheaper GPT-5.6 tier. Keep the current route when any of the following holds:
- The current route already meets the acceptance bar for that workload class and the candidate does not improve cost per accepted task.
- The candidate does not support a tool behavior your agent depends on, or supports it only through a shape your gateway cannot map.
- The workload is regulated and the candidate has not cleared data-residency, retention, or policy review.
- The candidate regresses p95 latency or cost per accepted task without a quality gain large enough to justify it.
- The returned model identity on the route is unclear, or usage and billing records do not reconcile with the requested model.
Routing exists to reserve expensive capability for the task classes where it changes the shipped outcome, not to send every request to the newest name.
A 5-Step Plan
- Freeze the baseline on Astra now. Save representative tasks, complete traces, evaluators, and current cost and latency numbers by workload class, with
gpt-6-astraon Responses. - Keep model selection in configuration. Route through the gateway so a future candidate is a config change, not a code change; do not spread provider IDs through application code.
- Write acceptance and rollback thresholds today. Accepted-task rate, cost per accepted task, p95 latency, error budget, and the rollback trigger, fixed before any candidate result is seen.
- Add Argon through the documented EvoLink route. Use the replay, shadow and canary sequence above; do not inherit Gemini 3.x limits or prices.
- Preserve the previous route through the observation window. Keep Astra (and the GPT-5.6 fallback) live until the candidate survives replay, shadow, and canary.
FAQ
Can I compare Gemini 4 and GPT-6 Astra directly today?
Yes: use EvoLink to run the same tasks on both routes. This article compares published evidence and defines the test; it does not report a completed EvoLink head-to-head experiment. Use each model page for current route pricing.
Do I need to migrate my API integration to use Gemini 4?
temperature, top_p, and none or minimal effort. A gateway's OpenAI-compatible endpoint keeps your key and base URL constant, but provider-native behavior such as tool schemas, streaming events, and reasoning controls still has to be verified per provider against the selected route documentation.How do I decide whether migration work is worth it?
Compare the cost of adapting and maintaining the integration with the measured benefit per accepted task. Keep the current route serving while you evaluate Argon; an API launch alone is not a reason to move all traffic.
How do I make tool calling comparable across providers?
Run a portable lane first: the same tool definitions, permissions, retry budget, and stop rules on both routes, with provider-specific features disabled. Then run native lanes (for Astra, async tool calling and mid-turn steering on Responses) and label them separately. Report whole-trace completion, wrong-tool rate, and loop rate per lane. Check which tool features the Argon route supports before including them in the portable lane.
When can Gemini 4 join production routing?
After your replay, shadow and canary results meet the quality, latency and cost thresholds fixed before testing. Use the documented EvoLink route, reconcile usage and billing, and keep Astra available for rollback.
Is GPT-6 Astra the same thing as Google's Project Astra?
gpt-6-astra. Google's Project Astra is an unrelated Google research and assistant project name. Neither is Gemini 4, and neither should be used as evidence about Gemini 4. Also keep Gemini 4 separate from Gemma 4, Google's open-weight model family.Sources
- Google's Argon announcement — September 30, 2026
- Google's published model evaluations
- Google: Alphabet Q2 2026 earnings letter (Gemini 4 pre-training statement)
- Google: Gemini 3.6 Flash announcement (Gemini 4 pre-training statement)
- Google: Gemini API model catalog
- OpenAI: GPT-6 Astra model documentation
- OpenAI: GPT-6 Astra announcement
- OpenAI API pricing
- OpenAI: latest model guidance (Responses-only tool calling, removed parameters)
- EvoLink Gemini 4 API status
- EvoLink GPT-6 Astra API
- EvoLink: Gemini 4 release date tracker
- EvoLink: Claude Fable 5.1 vs GPT-6 Astra


